Built to keep doing the work.
Reliability is more than whether a component is running. It is whether people can still do what they came to do.
Discuss your next stage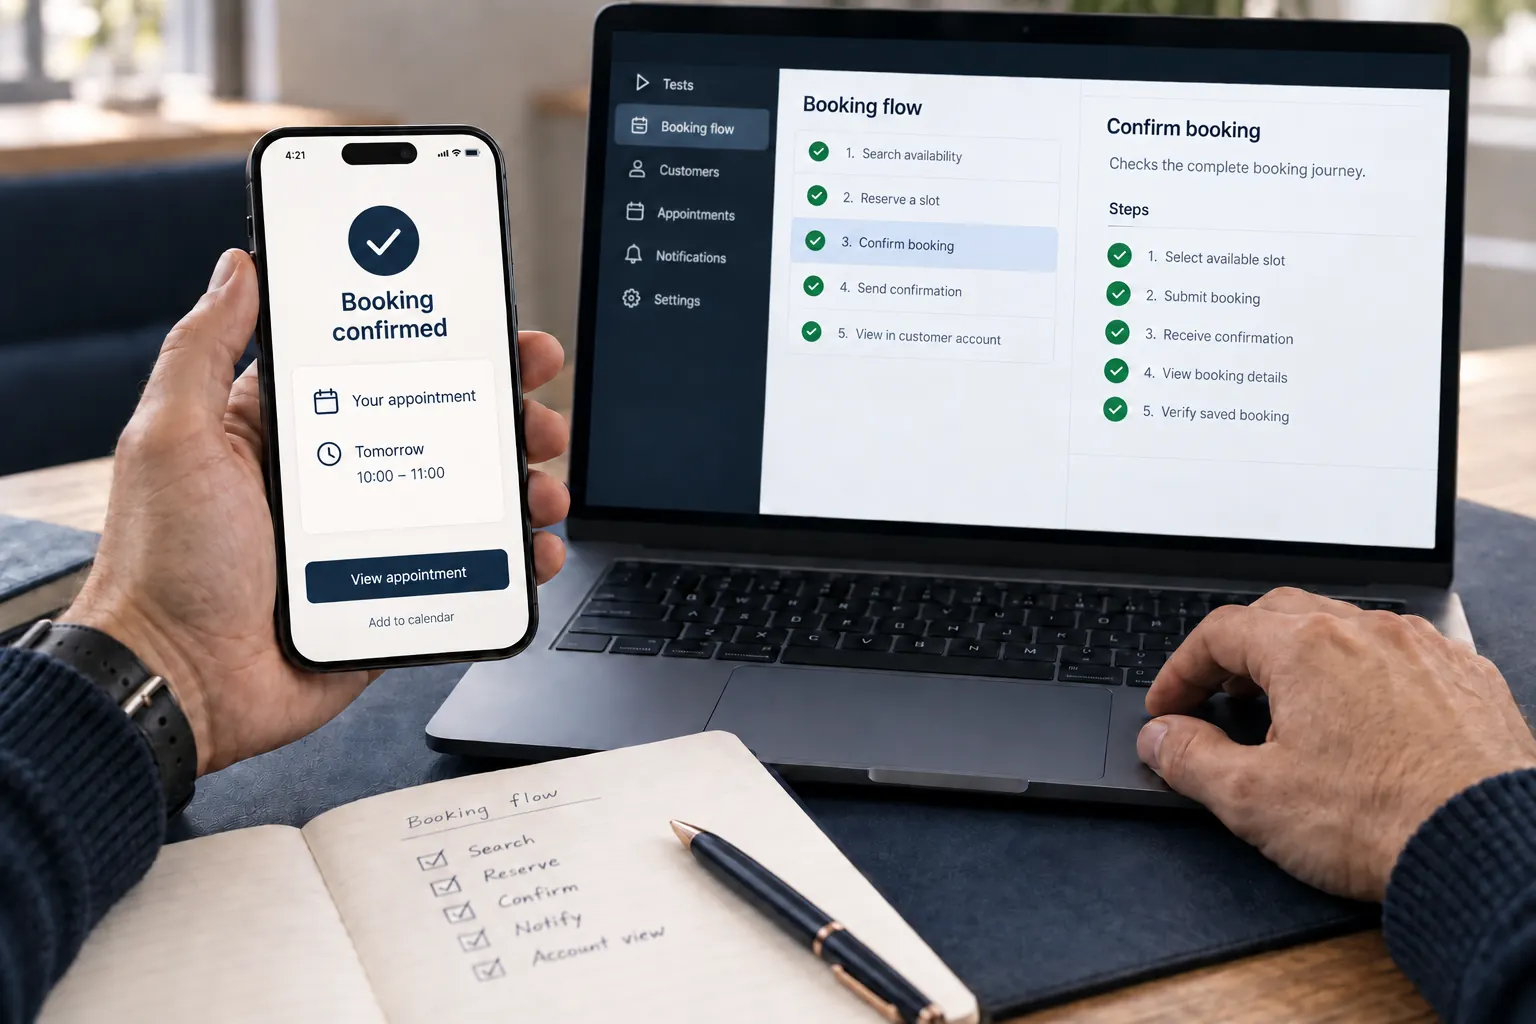
Reliability & performance,
in practice.
Make reliability a property of the whole system. Understand failure modes, recovery and performance under representative demand.
Follow the experience through the system.
A healthy application can still depend on an unreliable external service. A successful request can arrive too late to be useful. We look at the complete path from a customer action to its result, including dependencies, timeouts and the work happening in the background.
Design for the ordinary failure.
Networks time out. Releases contain mistakes. Services become unavailable. Understanding those conditions makes retries, backpressure, idempotency and recovery practical decisions rather than abstract best practices. The right level of resilience depends on what the business needs to protect.
Make recovery understandable.
An incident is easier to manage when signals are useful and responsibilities are clear. We consider observability, safe releases, backups and restore procedures together. A backup is a useful asset only when the data can actually be recovered within the time the business can tolerate.
The useful questions.
- What does a failure feel like to a customer?
- How would the team notice and investigate it?
- Which dependencies can stop an important journey?
- Has the recovery path been exercised?
Explore the thinking.
Read the related engineering noteA more dependable product starts here.
Which interruptions matter most to your customers? We help businesses with paying customers turn those questions into focused engineering work.
Discuss product reliability