What does “ready to scale” actually mean?
A practical way to connect growth plans to capacity, reliability and the ability to make changes.
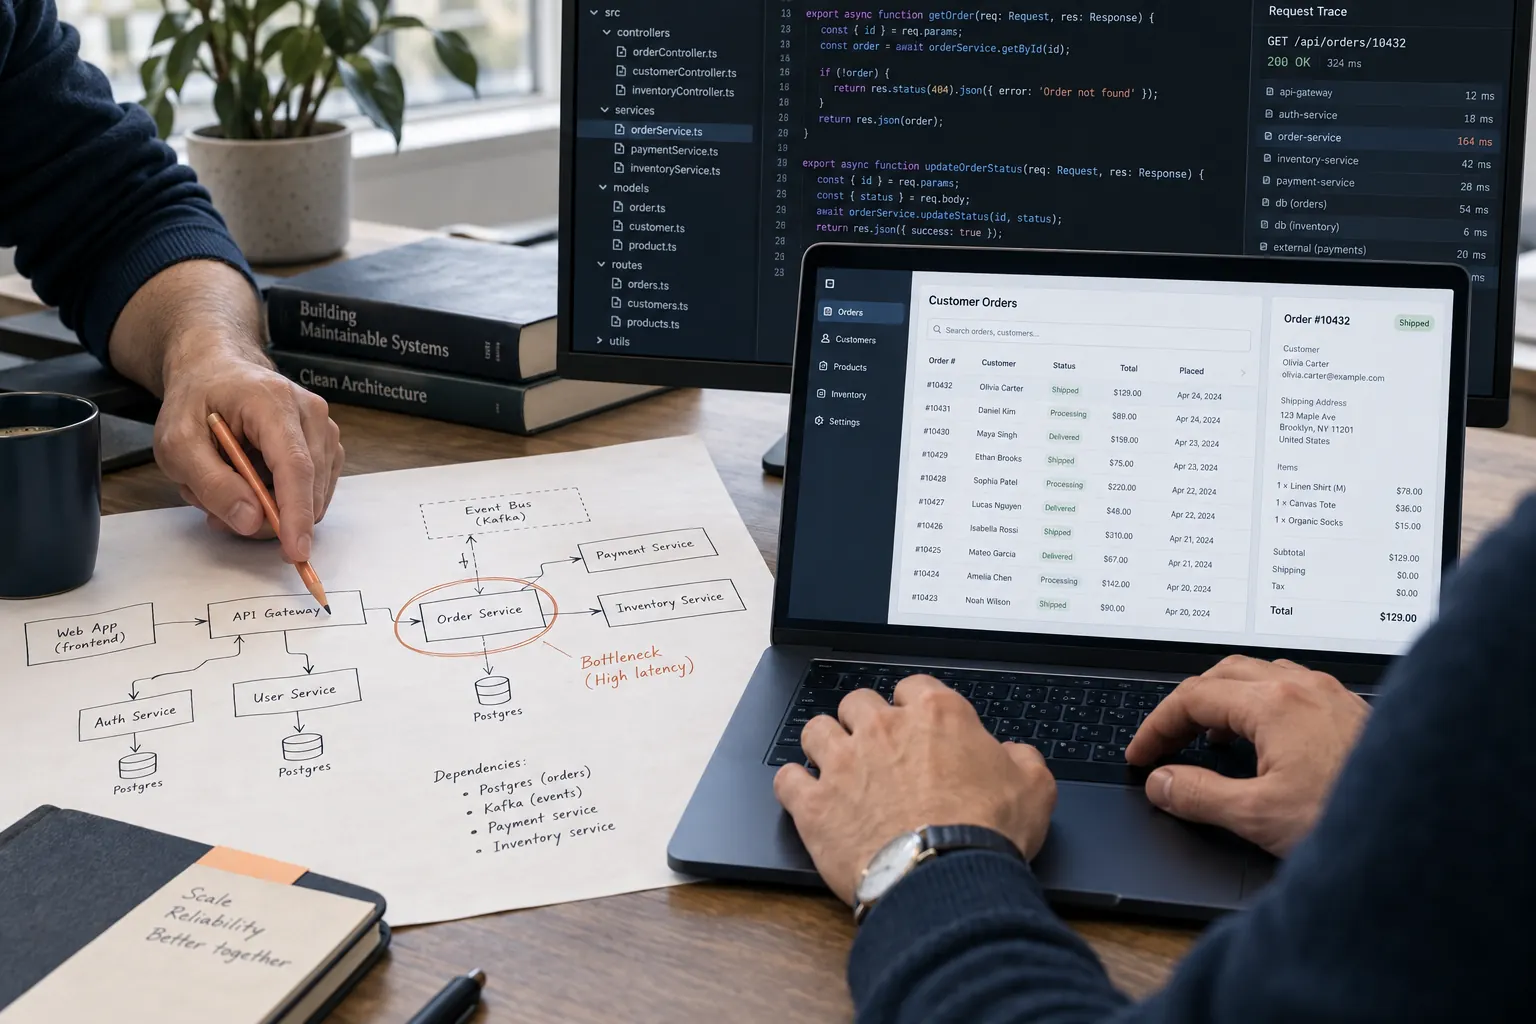
Readiness is a claim about a particular workload and customer experience. Make those conditions explicit before deciding what to build.
Describe the next stage in operational terms
“We need to scale” leaves too much room for interpretation. A larger customer base might mean more simultaneous sessions, larger customer datasets, more scheduled work or a wider range of integrations. Each puts pressure on a different part of the system. Begin by translating the business plan into the work the technology will actually perform.
A hypothetical reporting product may expect twice as many customers next quarter. If those customers upload much larger files and all generate reports at the start of the month, average daily traffic will tell an incomplete story. The relevant scenario combines file size, processing time and a concentrated burst of requests. Counting registrations alone misses those characteristics.
Write down a small number of plausible scenarios, their assumptions and the evidence behind them. Use customer conversations and observed usage where available. Forecasts remain uncertain, so avoid turning one optimistic number into an architectural requirement. A reasonable range helps the team decide what to measure now and which warning signals should prompt another review.
Define acceptable customer behavior
Readiness needs a definition of success. How quickly should an interactive action complete? How long can a background task take? Which operations must continue when a dependency is unavailable? A report completed later than usual may be acceptable; a confirmation that incorrectly says work is complete may not be.
A service level objective, or SLO, expresses a target for a measurable aspect of service quality. Google’s SRE guidance connects these objectives to user experience and prioritization. A useful first objective describes one important journey and specifies what counts as a good outcome, what is measured and over which period. The target should reflect the product’s needs rather than an impressive-looking number.
Be explicit about exclusions. A measure of successful server responses may exclude requests that never reach the server. A measure of completed jobs may hide jobs that were never accepted. These limitations do not make a metric useless, but they determine which conclusions it can support. Review the measurement with someone who understands the customer’s end-to-end experience.
Find capacity under representative conditions
Capacity is the amount of work the system can sustain while meeting its quality targets. A load exercise should therefore measure outcomes alongside resource use. Increasing requests until a server is busy is less informative than finding where the customer journey begins to slow, fail or accumulate unfinished work.
Use representative data shapes and request mixtures. A nearly empty database may make a query look harmless. Repeating one cached request may overstate practical capacity. Document the environment, dataset, workload and duration so another person can understand what the result means. A controlled test supports a statement about those conditions; it does not establish every possible production outcome.
Also examine what happens after demand falls. A queue can absorb a burst by holding work for later, as Microsoft’s load-leveling pattern describes, but that waiting work still has to be processed. If the backlog cannot drain before the next burst, the system is accumulating a problem. Track the age of the oldest unfinished task as well as the number waiting.
Check the ability to change and recover
A system can serve today’s requests and still be poorly prepared for growth. If each release requires a long outage, every customer increases the consequence of routine maintenance. If only one person can restore data, recovery depends on that person being available. These are constraints on the business even when performance charts look comfortable.
Ask for a demonstrated release path and a demonstrated recovery path. The release path should show how a small change moves through review, checks and deployment. The recovery path should show how the team returns to acceptable service when that change fails. Data changes deserve particular attention because returning to old application code may not undo a changed record.
Keep evidence separate. A successful restore in an isolated environment establishes that the tested backup and procedure worked there. It does not establish the exact time a live incident would take. Nevertheless, practicing that procedure reveals missing permissions, unavailable dependencies and unclear steps while there is room to repair them.
Make readiness a continuing decision
Bring the findings together in a short decision note. State the demand scenario, the customer outcome, the observed limit and the next action. Include confidence and uncertainty. “We have tested the expected burst with representative data, but have not tested a regional dependency failure” gives a founder something concrete to weigh.
Prioritize the smallest work that closes a consequential gap. That might be improving a query, separating a long task from an interactive request or making restoration repeatable. It may also mean adding capacity. The choice should follow the constraint rather than precede it.
Set a review trigger linked to usage or change. A new customer segment, a larger dataset or a different workload can invalidate earlier assumptions. Readiness is therefore maintained through observation and deliberate adjustment. The most useful outcome is a team that knows what its technology can presently support, where that knowledge ends and what evidence would justify the next investment.
Frequently asked questions
How do I know whether my product is ready to scale?
Define the demand you expect and the customer experience you need to preserve. Test representative journeys under that workload, check recovery from failures and confirm that the team can make and operate changes.
Is a high request-per-second number enough to prove readiness?
No. Capacity only describes the workload and conditions used in the test. Successful customer actions, response times, failure rates and recovery need to be considered alongside it.
Should we add more servers before testing the product?
First identify which resource or dependency limits the customer journey. Extra application servers may not resolve a database constraint or an external service limit. Choose the change after testing the relevant bottleneck.